



Offshore / Onsite
Hire Dedicated Team
Access a dedicated team of engineers and QA, on-site or remote, focused on your product and your roadmap.
Get StartedCloud and DevOps engineering with environments reproducible from a clean machine, alerts wired to thresholds that mean something, cost attributed per service rather than per invoice, and a rollback rehearsed before launch instead of during an incident.
Our Clients










Most infrastructure problems are invisible until an incident, a bill or an audit forces them into view. All four of these are cheap to fix in a quiet week and expensive to fix in a loud one.
Staging and production diverge quietly, so a change that passed staging fails live and nobody can say what differs.
Everything in Terraform, no console changes, and a fresh environment created from scratch on demand to prove it is reproducible.
The rollback exists in a document. During the incident it turns out the migration was not reversible and the plan was never run.
Rollback rehearsed on staging before launch, including the database path, with the runbook written from what actually happened.
Two hundred alerts a week, all ignored, so the one that mattered was muted six months ago along with the rest.
Alerts tied to user-visible symptoms and error budgets, tuned until every page is worth waking someone for.
A cloud bill goes up thirty per cent and nobody can attribute it to a service, a team or a customer.
Tagging enforced in code, per-service and per-tenant cost dashboards, and budget alerts that fire before the invoice does.
None of this is visible in the product. All of it decides how fast you can ship and how calm your incidents are.
Every resource in Terraform with remote state and review, so a new region or environment is a plan and an apply rather than a fortnight.
Build, test, security scan and deploy on every commit, with the gates that actually block: types, tests, coverage on critical paths and performance budgets.
Canary or blue-green deploys with automated rollback on error-rate regression, so a bad release is contained in minutes without a human decision.
Traces, metrics and logs correlated, with dashboards built around the questions your on-call rotation actually asks at 3am.
Tagging enforced at provision time, per-service and per-tenant attribution, rightsizing recommendations and budget alerts.
Secrets management, dependency and container scanning, least-privilege IAM and infrastructure policy checks, all failing the build rather than filing a ticket.
Nobody commissions infrastructure work when things feel fine. These are the events that usually trigger the call.
Releases happen on Thursday evenings with three people watching, which means they happen rarely and each one carries more risk.
The rollback did not work, nobody could find the right dashboard, and the post-mortem produced actions nobody has time for.
Cloud spend rose sharply and cannot be attributed. Finance wants a number per product and nobody can produce one.
SOC 2 or ISO 27001 needs evidence of access control, change management and monitoring that does not currently exist.
Traffic grew and the failure modes are new: connection limits, noisy neighbours, cold starts and queue backlogs.
The person who built the infrastructure has left, nothing is in code, and nobody wants to touch it.
Terraform modules across a dozen services, IAM policies per role, alert rules per endpoint, runbook entries per failure mode: high volume, highly patterned, and the work that quietly gets skipped when a deadline looms. Generating it means the pipeline actually gets the coverage it was supposed to have, inside the hours you budgeted.
Terraform modules, pipeline definitions and alert rules generated per service from an agreed pattern. Hand-writing the twelfth variant is where consistency usually breaks down.
Logs and traces correlated across services during an incident, and post-mortem timelines drafted from the telemetry rather than reconstructed from memory a week later.
IAM policies and security groups analysed for excess privilege across the whole estate — an audit that is tedious by hand and therefore rarely repeated.
Every Terraform change goes through plan review, every IAM change is approved deliberately, and no generated policy is applied because it looked reasonable. The speed is in drafting, never in applying.
See our AI practiceEvery change is reviewed as a plan diff by a named engineer. Generated infrastructure code is never applied unreviewed.
Least-privilege policies are security decisions. Suggestions are a starting point; the granted permission is chosen by a person.
A correlated root cause is a hypothesis until confirmed against the telemetry. Post-mortems are owned and signed by the responder.
We price platform work assuming this way of working, so the efficiency shows up in your quote rather than in our margin.
The test of infrastructure work is whether a new environment can be created from nothing, on a clean machine, by someone who did not build it. Everything we do is arranged to pass that test.
Every resource, every manual configuration, every undocumented dependency. Console-created resources are catalogued because they are what breaks a rebuild.
Existing resources imported or rebuilt in code, with modules per service and review on every change. Then we create a throwaway environment to prove it works.
Build, test, scan and deploy on every commit, with progressive rollout and automated rollback on error-rate regression. Deploys should be boring and frequent.
Traces, metrics and logs correlated, then alerts pruned to the ones worth waking someone for. An alert nobody acts on is worse than no alert.
A rollback actually performed on staging, including the database path, plus dependency failure drills. The runbook is written from what happened, not from what should.
In your cloud accounts, defined in code, reviewed through your process. Nothing here requires us to keep the lights on.




In your cloud accounts, defined in code, reviewed through your process. Nothing here requires us to keep the lights on.



In your cloud accounts, defined in code, reviewed through your process. Nothing here requires us to keep the lights on.



In your cloud accounts, defined in code, reviewed through your process. Nothing here requires us to keep the lights on.



In your cloud accounts, defined in code, reviewed through your process. Nothing here requires us to keep the lights on.


Case Studies
Selected work for retail, banking, telecom and defence teams, from brand identity and mobile apps to data platforms and AI assistants.
Panda
Reworked search, categories and checkout in Panda’s live app and website, in Arabic and English.
EDGE Group
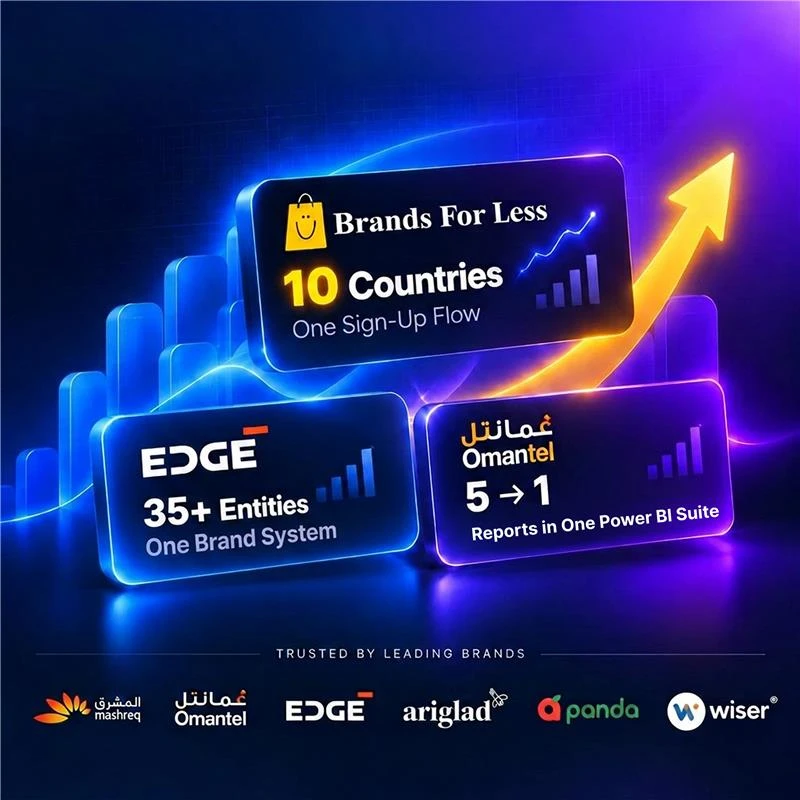
Brand identity, website and print for a group of 12,000 staff, carried onto the IDEX show floor.
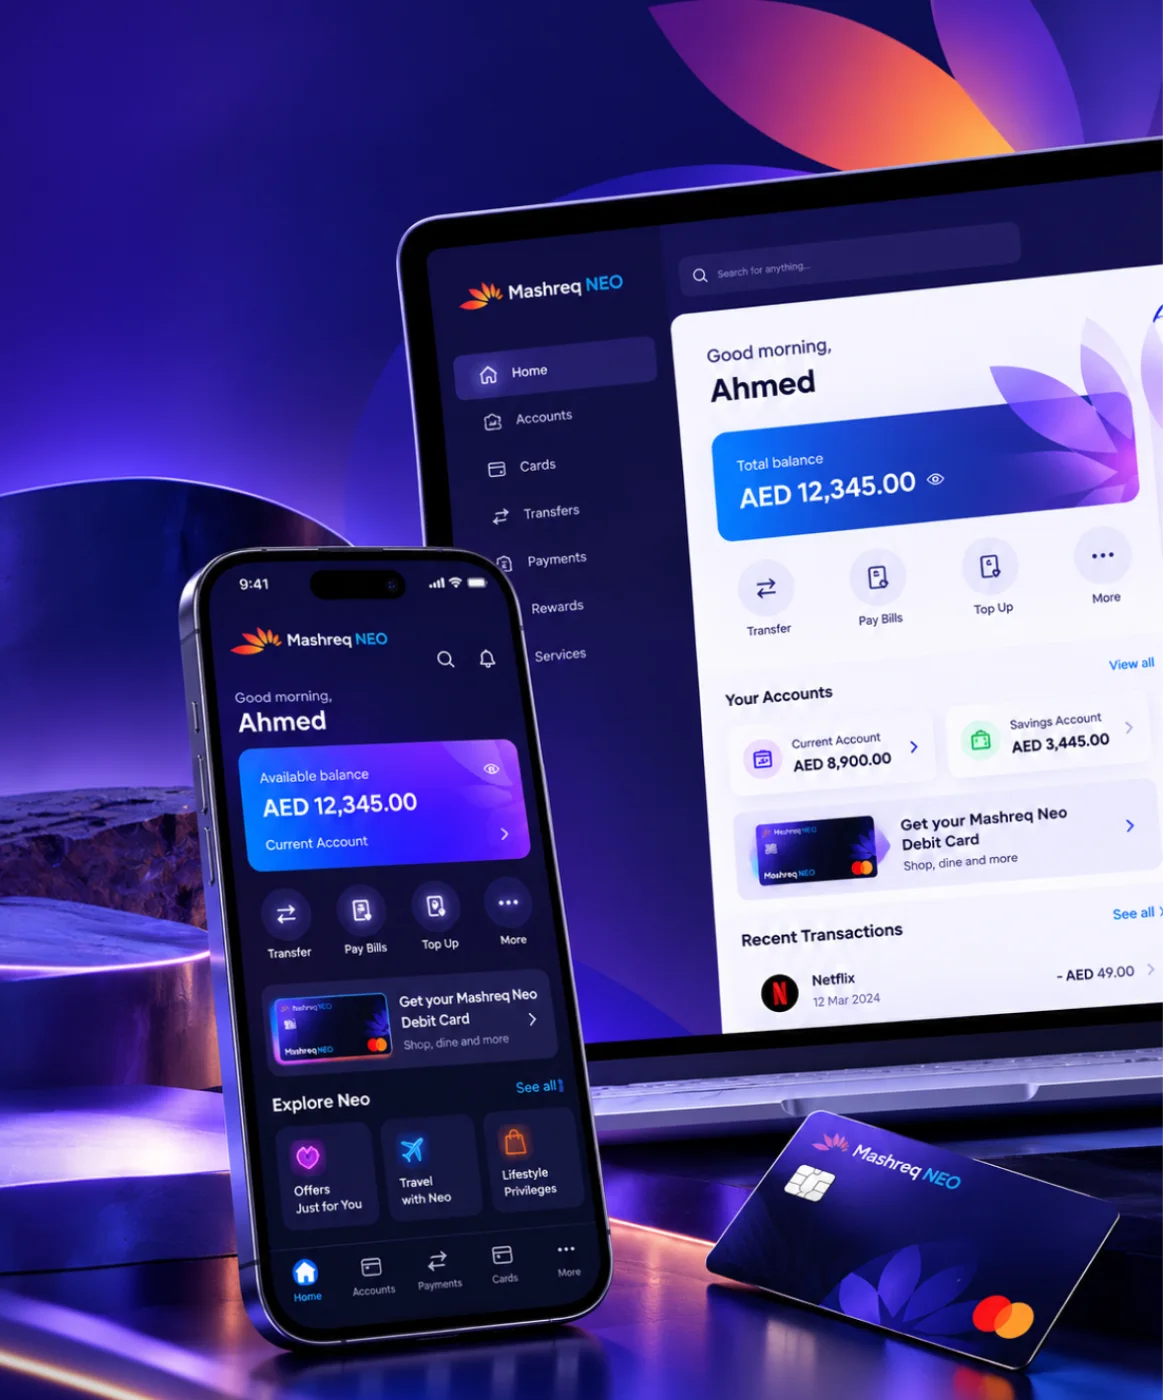
Mashreq NEO
Six performance areas in one index for leadership, plus NEO GPT, a private assistant for bank documents.
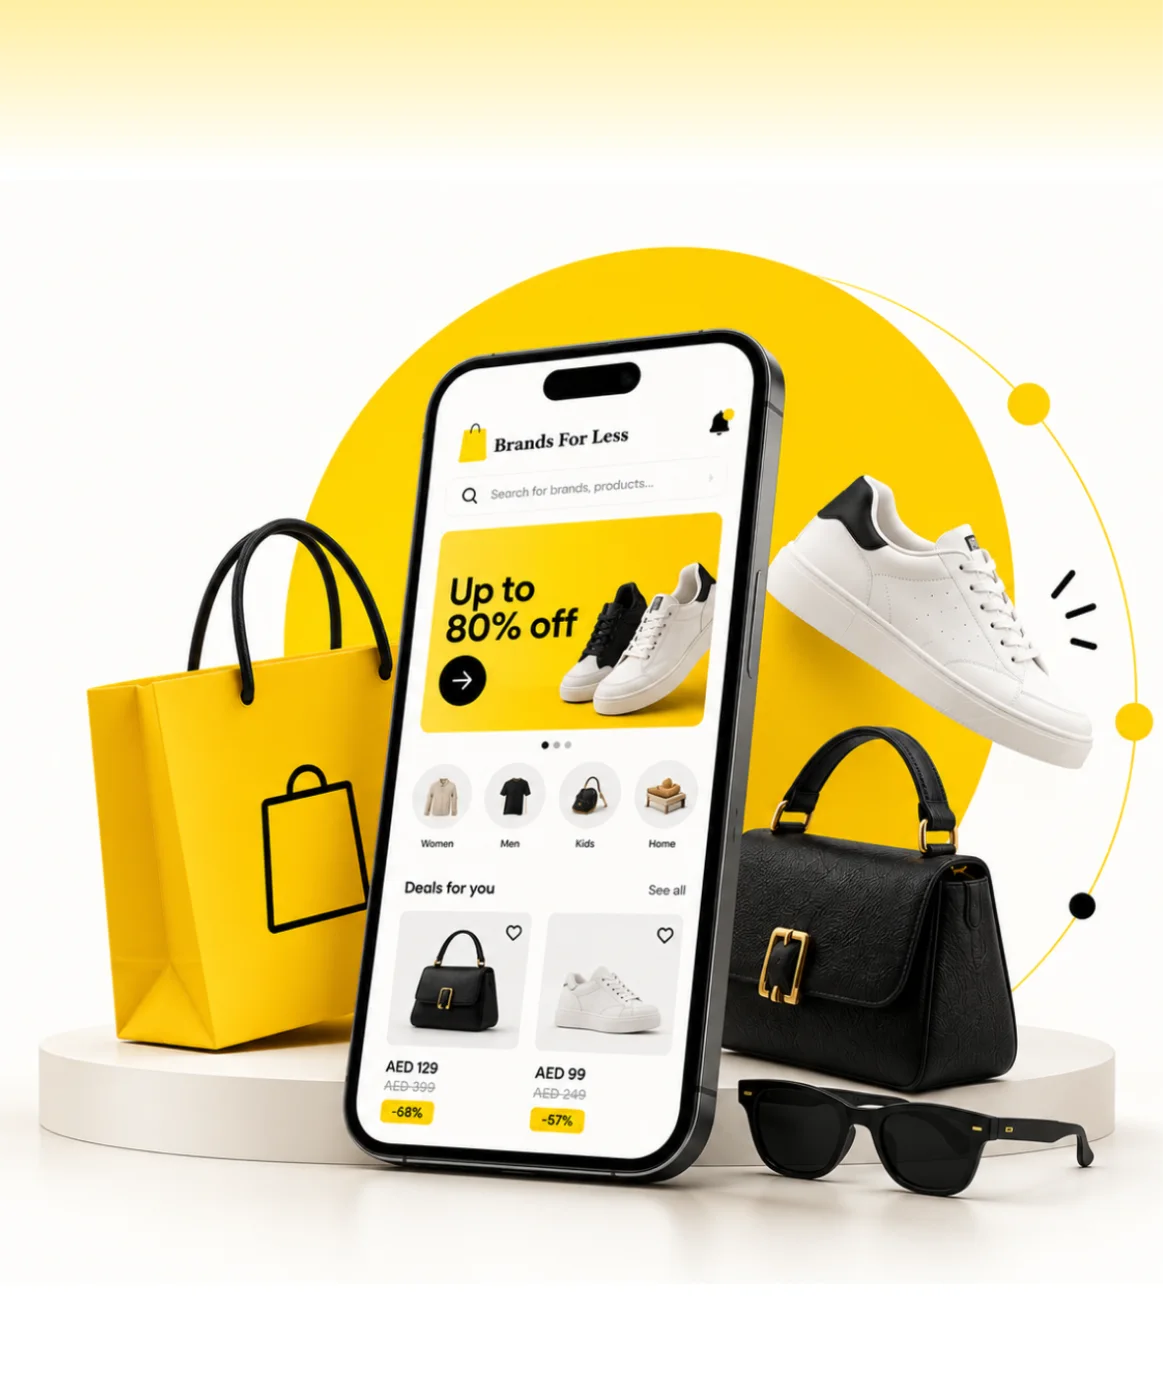
Brands For Less
Found where shoppers dropped off, then redesigned sign-up, banners and cart for a retailer with 120+ stores.
Omantel
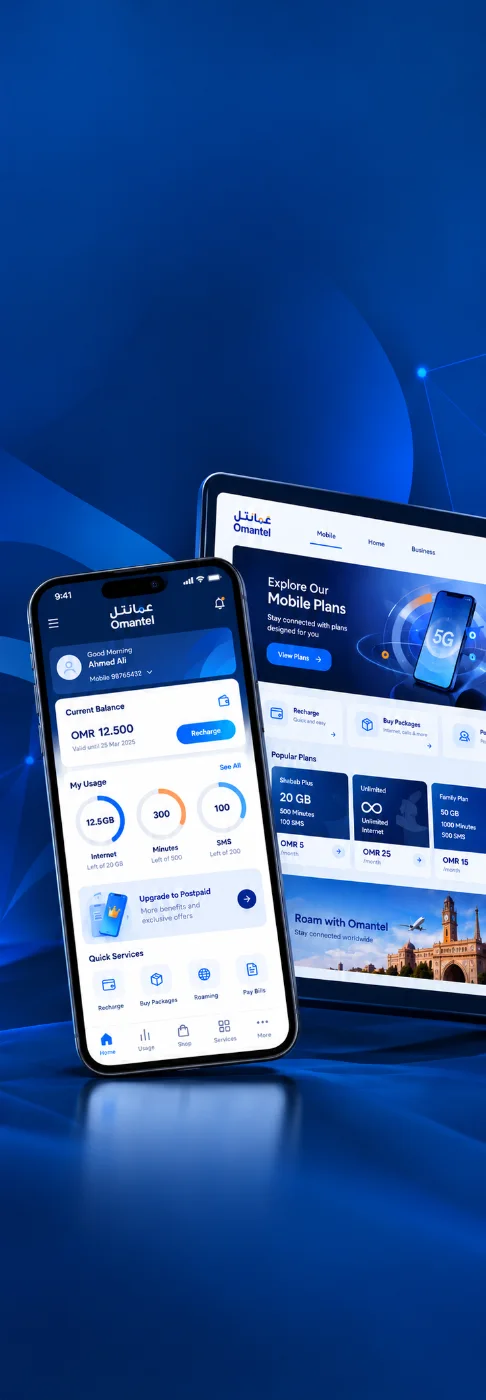
Incident, SLA and workload reporting in one Power BI suite for Oman’s first telecom operator.



Client Testimonials
Client Success: Panda
We reworked Panda's live app and website, from search to checkout, for shoppers across Saudi Arabia.
"Thanks to UIUX Studio’s work, the client successfully launched their websites. The team maintained a professional approach and scheduled frequent in-person meetings to provide suggestions for improving the project and ensuring its timely delivery."
 Shreya LadCEO, Nutroponics
"The team is well-versed in the UI/UX domain and has designed a fantastic journey to support the site’s growth projection. Communication, timeliness, and quality of work have been very professional."
 Mohammed AbdullahZeaara.com
"The Studio has been an absolute game changer for us. After working on a few independent projects, they are now also helping our marketing team, proving their value to our business and earning praise from executives."
 BrandonProject Manager
"The UIUX Studio team consistently delivers exceptional work with dedication. We’ve completed an amazing app design together, and I’m excited to collaborate with them again in the future."
 Hani Farajvancouverhousefinders.com
"We are really pleased with the work that UIUX Studio team has completed for us in designing a website for a new brand. They completed the designs quickly, took on board changes, and the finished product is very professional."
 AnayaHead of Marketing, Freshminds
"I’ve worked with UIUX Studio team on two projects. They capture the vision and run with it! They create exceptional design! Couldn’t be happier with the quality work and files for my developers."
 Brandon PugmirePresident, Imprint City
 Client Results
Reviewed on Upwork, Trustpilot, Clutch, G2 and GoodFirms


Work With Us
UIUX Studio offers flexible software development services with dedicated teams to meet your business needs. Whether you need an end-to-end build or specialised engineering expertise, our engagement models give you the support to launch and scale.
Access a dedicated team of engineers and QA, on-site or remote, focused on your product and your roadmap.
Get StartedGet clear, upfront pricing for a defined build, such as an MVP, an integration or a platform migration.
Get StartedGet expert engineers by the hour, perfect for code reviews, bug fixes, small features or architecture advice without a long-term commitment.
Get StartedUptime alone hides too much. These six are the ones that predict whether the next incident goes well.
How often you can ship. Low frequency is almost always a confidence problem rather than a capacity one.
Commit to production. Long lead times mean the pipeline is doing something a human should not have to wait for.
Deploys needing a fix or rollback. This is where progressive delivery earns its keep.
Detection to resolution. Improved by rehearsed rollback and dashboards someone can read at 3am.
Attributed rather than estimated, with month-on-month movement explained rather than noticed.
Share of alerts that led to a real action. Low ratios mean the alerting is training people to ignore it.
From retail apps and banking dashboards to a defence group rebrand, we bring proven domain knowledge to every product we design and build.
Talk to Our Team
Streaming, OTT & content platforms

Fan engagement & live data

EdTech & learning platforms

AdTech & campaign tooling

PropTech & marketplaces
Payments, banking & wealth

Digital health & patient apps
Retail & D2C platforms
Supply chain & fleet ops
B2B products & dashboards
Platform work exists to make everything else safe to ship, so it is scoped alongside most other engineering.
The applications deploying through this pipeline, with budgets and tests enforced by the same gates.
View service ↗Per-tenant cost visibility, progressive delivery and the isolation guarantees a platform needs.
View service ↗Scanning, penetration testing and the compliance evidence an audit will ask for.
View service ↗Where the immediate question is spend rather than delivery, under technology advisory.
View service ↗Forty-five minutes with a platform engineer. We will find out whether you could rebuild your environment from scratch, whether the rollback has ever been run, and what your bill is hiding. No deck, no audit fee.
Review your pipelineBook a free consultation with our design, engineering and AI experts. Share your idea and we’ll come back within one business day with clear next steps.
Recognised By


Our Offices

UAE · Headquarters
Office OFF2-127, SMARK 2 Building, Plot No. 33-0, Ras Al Khor Industrial Second, Dubai, UAE

India
B-409, Bestech Business Tower, Sector 66, SAS Nagar, Punjab 160062

Australia
Tapleys Hill Road, Fulham Gardens, SA 5024