



Offshore / Onsite
Hire Dedicated Team
Access a dedicated RevOps specialist or team, on-site or remote, who runs forecasting, reporting and CRM requests alongside your sales team.
Get StartedA lead scoring model built from closed-won history rather than from a workshop, with enrichment strategy, routing that prioritises for reps, and quarterly recalibration against outcomes. Combining fit and intent into one number is why most scoring gets ignored.
Our Clients










Most scoring models are abandoned within two quarters, and it is almost never because the maths was wrong. Four design mistakes make a score unusable regardless of how well it predicts.
A perfect-fit account browsing pricing scores the same as a poor-fit account downloading everything. The action required is completely different.
Two separate axes. High fit with low intent is a nurture case; low fit with high intent is a disqualification. One number hides both.
Points assigned by opinion — fifty for a demo request, ten for a whitepaper — with no evidence either correlates with closing.
Weights derived from what actually preceded closed-won deals, tested against held-out history before anything goes live.
Reps see a number and no instruction. Without a defined action per band, the score is decoration on a record.
Bands with a required action and a routing rule, so the score changes what happens rather than merely describing it.
A model trained on last year’s mix, still running after a segment change, quietly scoring the wrong things.
Quarterly recalibration against actual outcomes, with drift reported so decay is visible rather than gradual.
A model, the routing that acts on it, and the recalibration loop that keeps it honest. Without all three it decays within two quarters.
Firmographic and technographic criteria weighted by what closed-won accounts actually look like, with the disqualifying attributes named explicitly.
Behavioural signals weighted by what genuinely preceded closing — not every tracked action, only the predictive ones.
Which data sources fill which fields, at what cost per record, and what happens when enrichment fails or conflicts.
What a rep does at each combination of fit and intent, with routing and SLA attached so the score drives behaviour.
The model tested on held-out closed deals before launch, so its predictive value is measured rather than assumed.
A quarterly refresh against outcomes, with drift reported, so the model tracks your business as the mix moves.
Scoring earns its place when there are more leads than capacity and prioritisation has become a real decision.
Volume exceeds capacity, so the question is no longer whether to follow up but in what order.
A model exists, reps do not use it, and nobody has checked whether it predicts anything.
SDRs working leads that were never going to buy, which is expensive and demoralising in equal measure.
Usage signals available and unused, which are usually far more predictive than firmographic fit alone.
Paying for data enrichment with no evidence it improves conversion or routing.
Moving upmarket, and the old scoring criteria now describe accounts you no longer want.
A good scoring model requires testing dozens of candidate signals against thousands of closed deals, then validating on held-out data. That is arithmetic at a volume nobody does by hand, which is why most models are built from workshop opinion instead. Doing it properly is now a four-week engagement rather than a quarter.
Every available firmographic and behavioural signal tested for correlation with closing, so the weights come from evidence rather than from a room full of assumptions.
Records matched and deduplicated across enrichment sources, with conflicts surfaced rather than silently overwritten.
Ongoing comparison of predicted against actual outcomes, so decay is reported the quarter it starts rather than noticed a year later.
A model finds correlation. Which segments you want, and which you decline regardless of intent, is strategy — and it is set by your leadership rather than inferred from last year’s wins.
See our AI practiceThe model is tested against closed deals it never saw before it goes live. A model that only fits its training data is worse than no model.
What a rep does at each band is negotiated with sales leadership, because a score without an agreed action is ignored.
Which accounts you decline is a commercial choice, documented and owned, never something the model decides on its own.
Where two sources disagree, the conflict is flagged rather than silently resolved by whichever ran last.
The model is the easy part once the history is read. The engagement is agreeing what a rep does at each band, because a score with no attached action gets ignored within a month.
What your winning accounts actually had in common, and what preceded the close. Dozens of candidate signals tested rather than the handful anyone assumed.
Fit from firmographics, intent from behaviour, kept separate because they demand different actions. Validated on held-out deals before anyone sees a score.
Which sources fill which fields, cost per record, and conflict handling. A model on incomplete data scores the completeness rather than the account.
What happens at each fit and intent combination, agreed with sales leadership and built into routing so the score drives behaviour rather than describing it.
Rolled out with training, then a quarterly recalibration process and drift reporting so the model tracks your business as the mix changes.
Your CRM and automation platform, with the model documented so your team can maintain and re-run it.


Your CRM and automation platform, with the model documented so your team can maintain and re-run it.


Your CRM and automation platform, with the model documented so your team can maintain and re-run it.


Your CRM and automation platform, with the model documented so your team can maintain and re-run it.



Your CRM and automation platform, with the model documented so your team can maintain and re-run it.


Case Studies
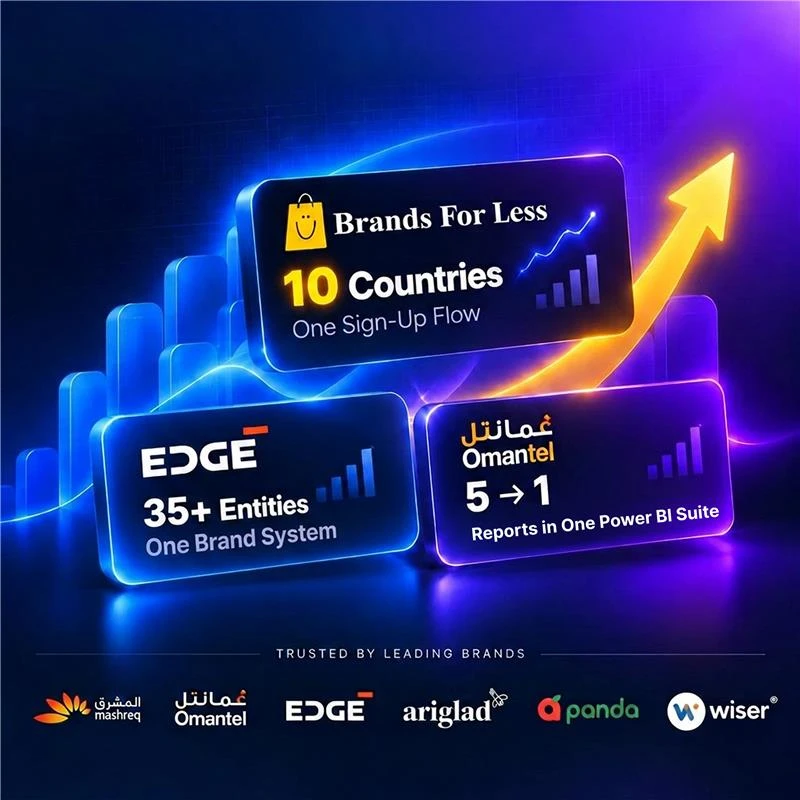
Selected work for retail, banking, telecom and defence teams, from brand identity and mobile apps to data platforms and AI assistants.
Panda
Reworked search, categories and checkout in Panda’s live app and website, in Arabic and English.
EDGE Group
Brand identity, website and print for a group of 12,000 staff, carried onto the IDEX show floor.
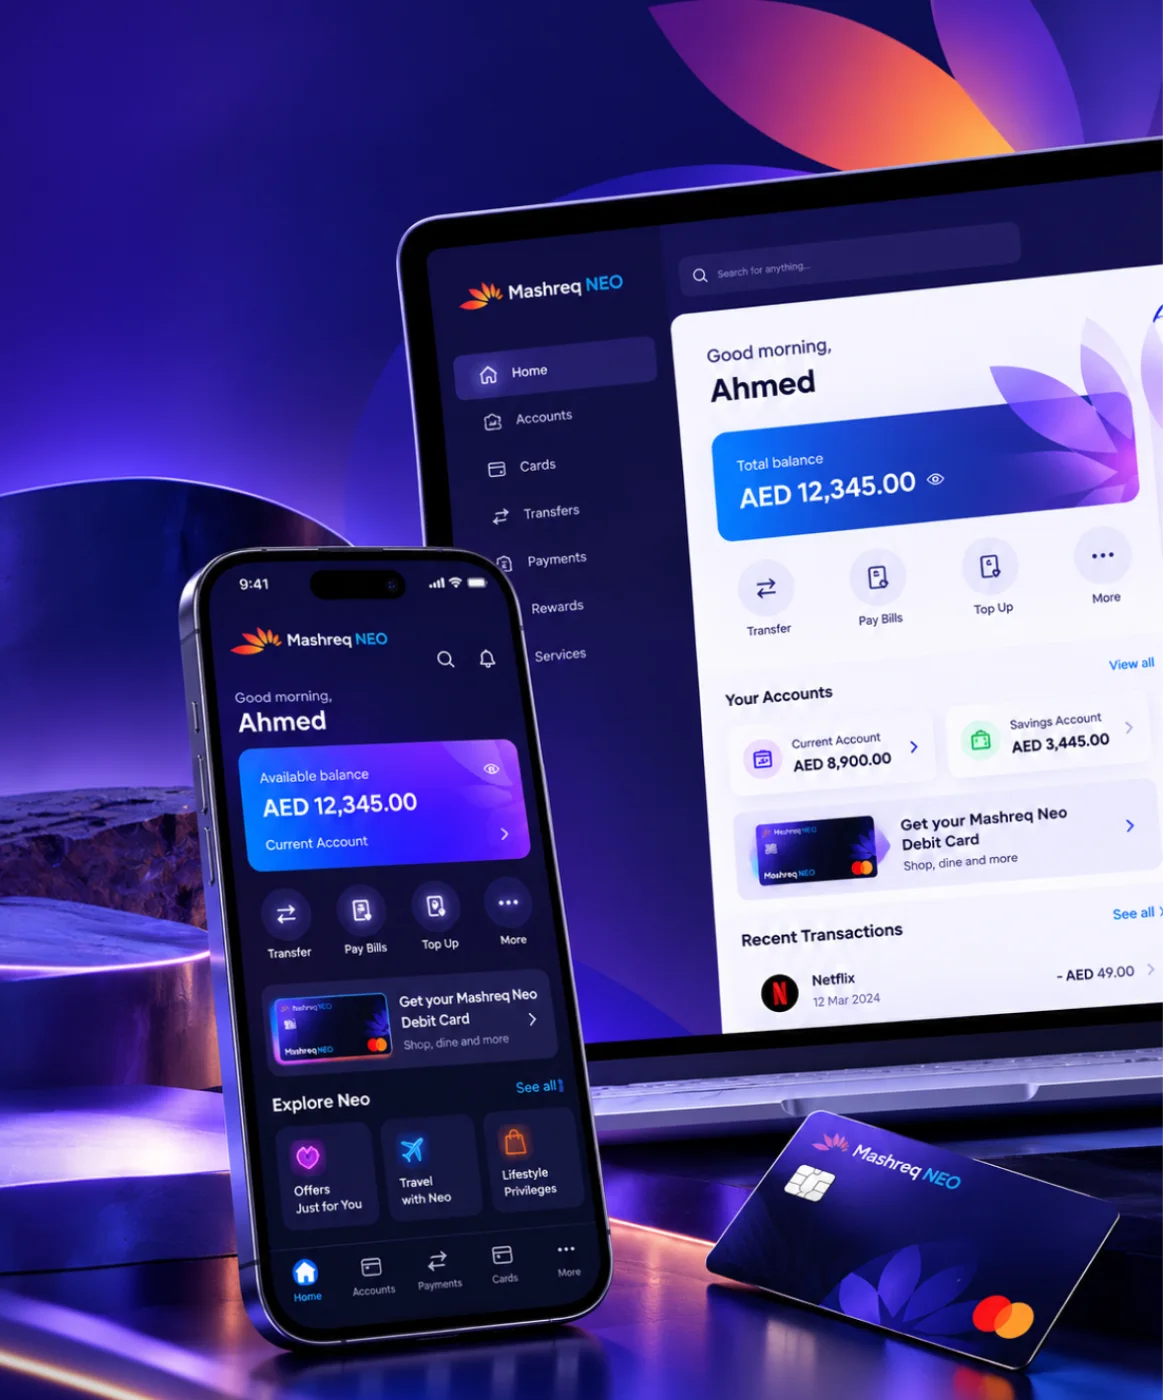
Mashreq NEO
Six performance areas in one index for leadership, plus NEO GPT, a private assistant for bank documents.
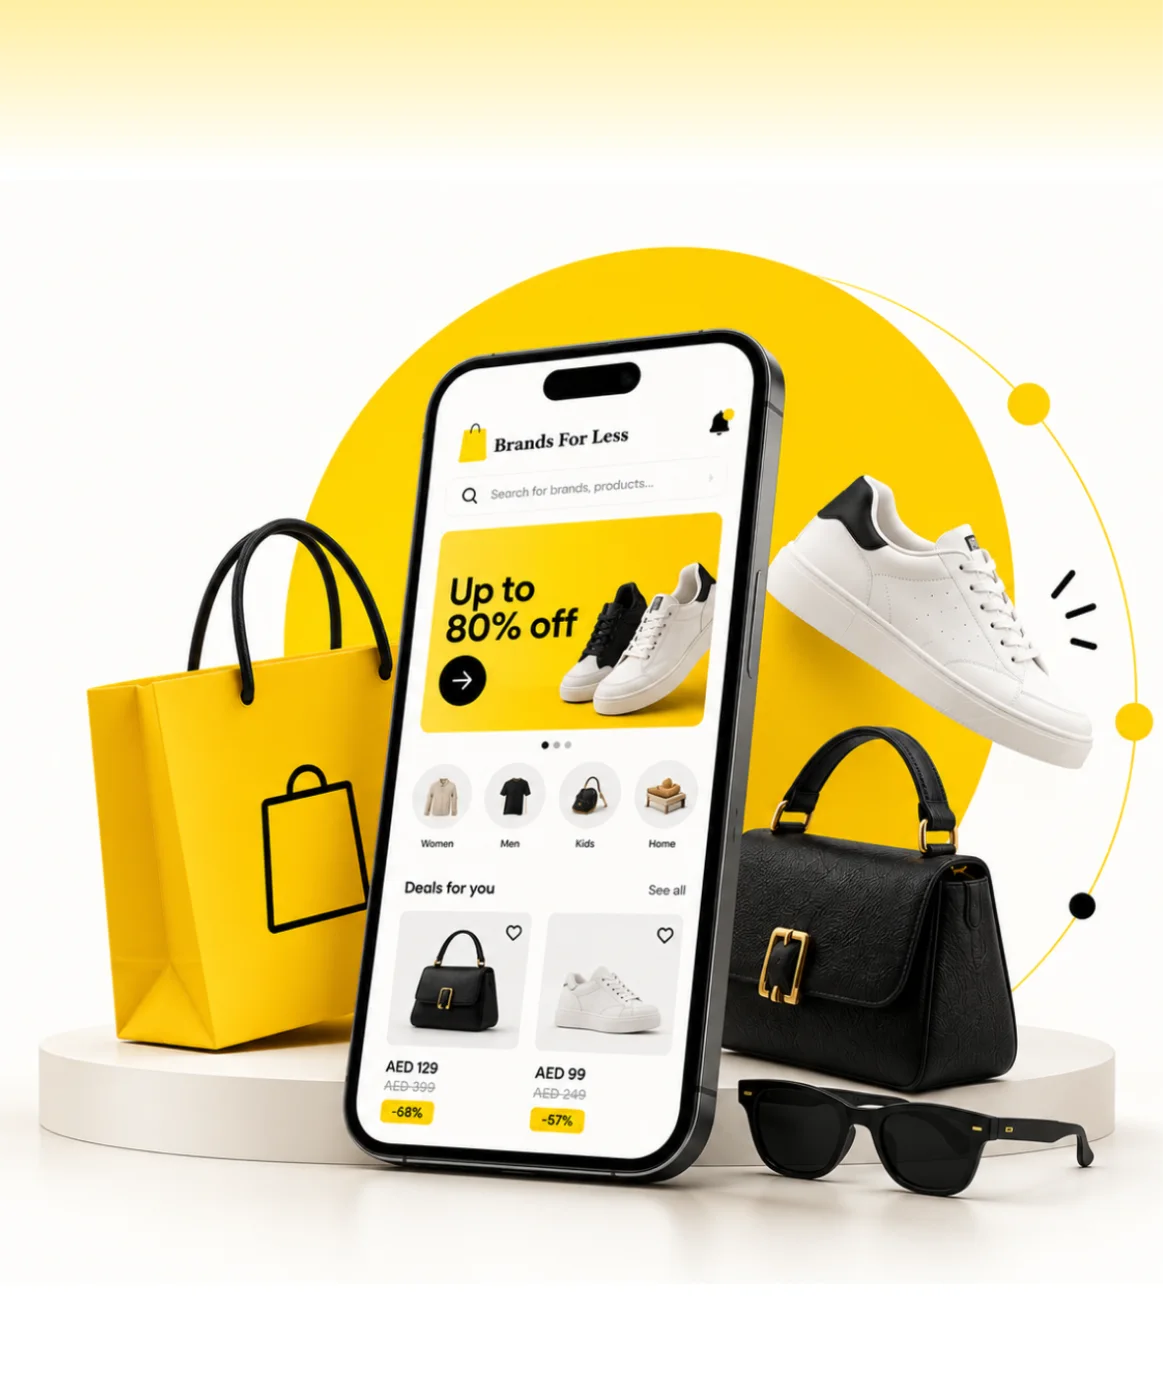
Brands For Less
Found where shoppers dropped off, then redesigned sign-up, banners and cart for a retailer with 120+ stores.
Omantel
Incident, SLA and workload reporting in one Power BI suite for Oman’s first telecom operator.



Client Testimonials
Client Success: Panda
We reworked Panda's live app and website, from search to checkout, for shoppers across Saudi Arabia.
"Thanks to UIUX Studio’s work, the client successfully launched their websites. The team maintained a professional approach and scheduled frequent in-person meetings to provide suggestions for improving the project and ensuring its timely delivery."
 Shreya LadCEO, Nutroponics
"The team is well-versed in the UI/UX domain and has designed a fantastic journey to support the site’s growth projection. Communication, timeliness, and quality of work have been very professional."
 Mohammed AbdullahZeaara.com
"The Studio has been an absolute game changer for us. After working on a few independent projects, they are now also helping our marketing team, proving their value to our business and earning praise from executives."
 BrandonProject Manager
"The UIUX Studio team consistently delivers exceptional work with dedication. We’ve completed an amazing app design together, and I’m excited to collaborate with them again in the future."
 Hani Farajvancouverhousefinders.com
"We are really pleased with the work that UIUX Studio team has completed for us in designing a website for a new brand. They completed the designs quickly, took on board changes, and the finished product is very professional."
 AnayaHead of Marketing, Freshminds
"I’ve worked with UIUX Studio team on two projects. They capture the vision and run with it! They create exceptional design! Couldn’t be happier with the quality work and files for my developers."
 Brandon PugmirePresident, Imprint City
 Client Results
Reviewed on Upwork, Trustpilot, Clutch, G2 and GoodFirms


WORK WITH US
UIUX Studio offers flexible RevOps consulting with dedicated specialists who work in your existing CRM. Whether you need a full RevOps rebuild or help with a single report, our engagement models give you the support to forecast with confidence.
Access a dedicated RevOps specialist or team, on-site or remote, who runs forecasting, reporting and CRM requests alongside your sales team.
Get StartedGet clear, upfront pricing for a defined project, such as a pipeline audit, a RevOps rebuild or a CRM migration.
Get StartedGet RevOps help by the hour, perfect for CRM fixes, new reports, workflow changes or a quick forecast check.
Get StartedAverage score is meaningless. These tell you whether the model is earning its place.
Whether high-scoring leads actually convert better. If the bands do not separate, the model is not working.
Whether the agreed action per band is actually taken. A model nobody follows predicts nothing useful.
How much better the model is than working leads in arrival order. This is the honest measure of its value.
Whether declined leads genuinely would not have closed, checked periodically so the model is not silently excluding good accounts.
Share of records successfully enriched and the cost per record, against the conversion lift it produces.
Predicted against actual over time. Rising divergence means recalibration is due rather than optional.
From retail apps and banking dashboards to a defence group rebrand, we bring proven domain knowledge to every product we design and build.
Talk to Our Team
Streaming, OTT & content platforms

Fan engagement & live data

EdTech & learning platforms

AdTech & campaign tooling

PropTech & marketplaces
Payments, banking & wealth

Digital health & patient apps
Retail & D2C platforms
Supply chain & fleet ops
B2B products & dashboards
Scoring is a prioritisation layer on top of pipeline definitions and clean data, so it is rarely bought alone.
The qualified definition the score has to serve, agreed by both teams.
View service ↗Where the score, routing and SLA actually live and get enforced.
View service ↗Deduplication and account hierarchy, without which scoring runs on unreliable records.
View service ↗Where a genuinely predictive model with retraining and monitoring is warranted.
View service ↗Forty-five minutes with a RevOps lead. We will test whether high-scoring leads actually convert better, which signals you are missing, and whether the bands have any action attached. No deck, no audit fee.
Score what mattersBook a free consultation with our design, engineering and AI experts. Share your idea and we’ll come back within one business day with clear next steps.
Recognised By


Our Offices

UAE · Headquarters
Office OFF2-127, SMARK 2 Building, Plot No. 33-0, Ras Al Khor Industrial Second, Dubai, UAE

India
B-409, Bestech Business Tower, Sector 66, SAS Nagar, Punjab 160062

Australia
Tapleys Hill Road, Fulham Gardens, SA 5024