


Offshore / Onsite
Hire Dedicated Team
Access a dedicated team of AI engineers and designers, on-site or remote, who build and run your agents alongside your team.
Get StartedMachine learning for forecasting, recommendation, classification and vision — the problems where a general-purpose model is the wrong tool and a model trained on your history is the right one. Deployed into the product, monitored for drift, retrained on a schedule.
Our Clients










Language models are extraordinary at language and mediocre at arithmetic over your history. When the question is how much, how many or which one, a trained model is usually cheaper, faster and more accurate — by a wide margin.
Open-ended text, a summary, a draft, an explanation in someone's own words.
A number, a probability, a rank or a label from a fixed set that you will act on automatically.
Hundreds of calls a day, and a second or two of waiting is acceptable to the user.
Millions of predictions, inline in a page load. Inference measured in milliseconds and fractions of a cent.
In general world knowledge, or in a document the model can be handed at request time.
In patterns across years of your own transactions that no general model has ever seen.
A plausible narrative, which is not the same as the actual reason and cannot be audited as one.
Feature attributions built for regulatory review, consistent across every prediction.
A model in a notebook is a finding. These are the pieces that turn it into something your product depends on and your team can keep running.
The transformations from raw data to model input, written once and used identically in training and serving. This is where most silent failures originate.
The model, plus the simple heuristic it has to beat. If a three-line rule performs within a point of it, we say so rather than shipping complexity.
Inference behind an API with the latency your product needs, batch or real time, and a defined behaviour when the model is unavailable.
Input distributions and prediction quality tracked in production, with alerts when the world moves away from the training data.
Scheduled or triggered retraining with validation gates, so refreshing the model is a routine job rather than a project.
Feature attributions per prediction, and bias testing across the groups your regulator or your ethics review will ask about.
All of these share one thing: you already have years of labelled outcomes sitting in a database, and nobody is using them.
SKU and location-level forecasts that beat the spreadsheet consensus, feeding purchasing and inventory rather than a monthly slide.
Which accounts are drifting, scored weekly with the reasons attached, early enough for the conversation to be about value rather than discount.
Ranking tuned on your own conversion data, not a generic collaborative filter that treats your catalogue like everyone else’s.
Patterns across transactions that rules keep missing, with a threshold set by what a false positive actually costs you.
What a price change does to volume and margin by segment, modelled from your own history rather than assumed.
Defect detection, document classification and image tagging trained on your own images, running at line speed.
Every engagement starts by measuring what you do today and building the simplest thing that could work. Sophistication has to justify itself against that number, not against a benchmark from a paper.
What decision the prediction feeds, who makes it today and how well they do. Without a current-state number there is nothing to beat and no way to know whether the project worked.
How much labelled history exists, how clean it is, and whether the features available at prediction time match the ones available in hindsight. Leakage kills more projects than model choice.
The naive rule and a first trained model, scored on the same holdout. If the gap is small we say so, and the honest recommendation is often to ship the rule.
Feature pipeline shared between training and serving, inference behind an API at the latency your product needs, and integration into the workflow that acts on the output.
Drift detection on inputs and outputs, scheduled retraining with validation gates, and training for the team who will own it. A model nobody can retrain has a shelf life of months.
Standard, boring, well-supported tooling in your cloud account. Novel frameworks are a liability on something your team has to maintain for years.



Standard, boring, well-supported tooling in your cloud account. Novel frameworks are a liability on something your team has to maintain for years.




Standard, boring, well-supported tooling in your cloud account. Novel frameworks are a liability on something your team has to maintain for years.


Standard, boring, well-supported tooling in your cloud account. Novel frameworks are a liability on something your team has to maintain for years.


Standard, boring, well-supported tooling in your cloud account. Novel frameworks are a liability on something your team has to maintain for years.

Case Studies
Selected work for retail, banking, telecom and defence teams, from brand identity and mobile apps to data platforms and AI assistants.
Panda
Reworked search, categories and checkout in Panda’s live app and website, in Arabic and English.
EDGE Group
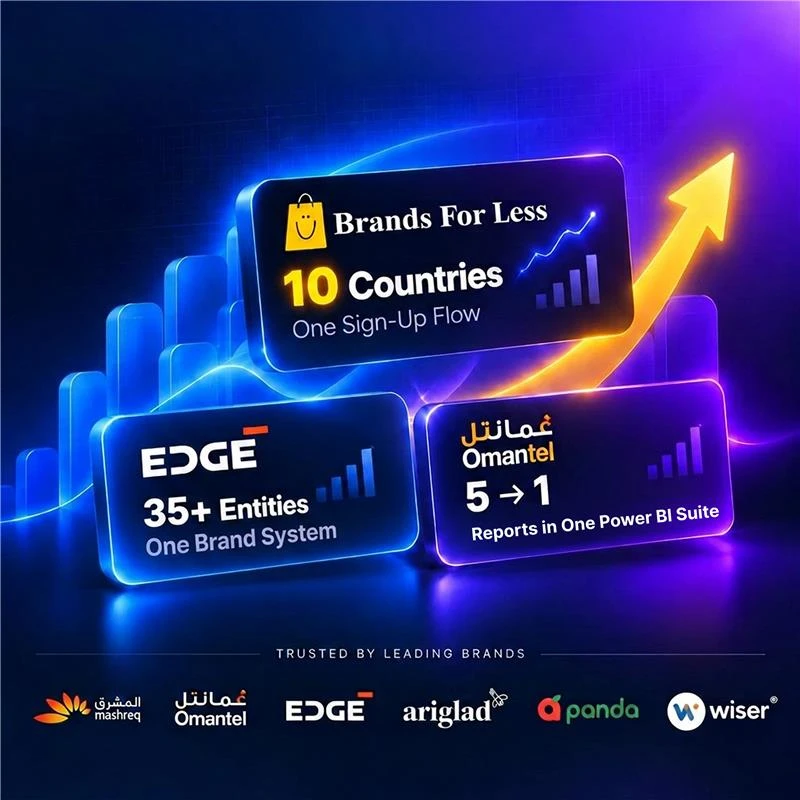
Brand identity, website and print for a group of 12,000 staff, carried onto the IDEX show floor.
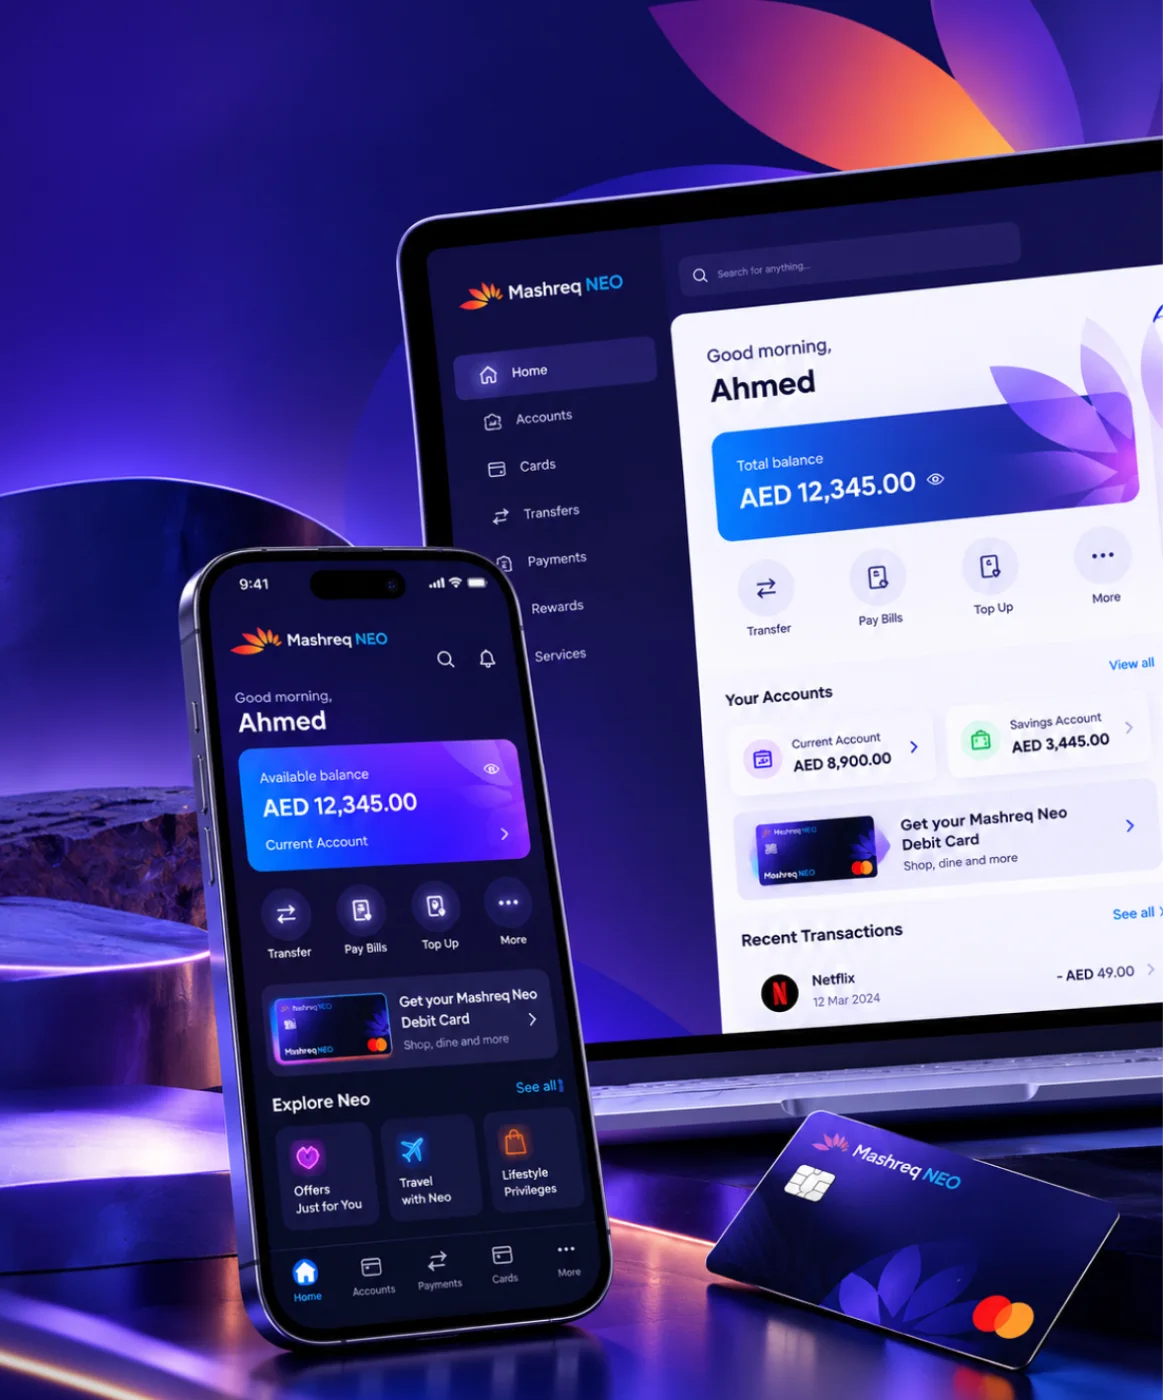
Mashreq NEO
Six performance areas in one index for leadership, plus NEO GPT, a private assistant for bank documents.
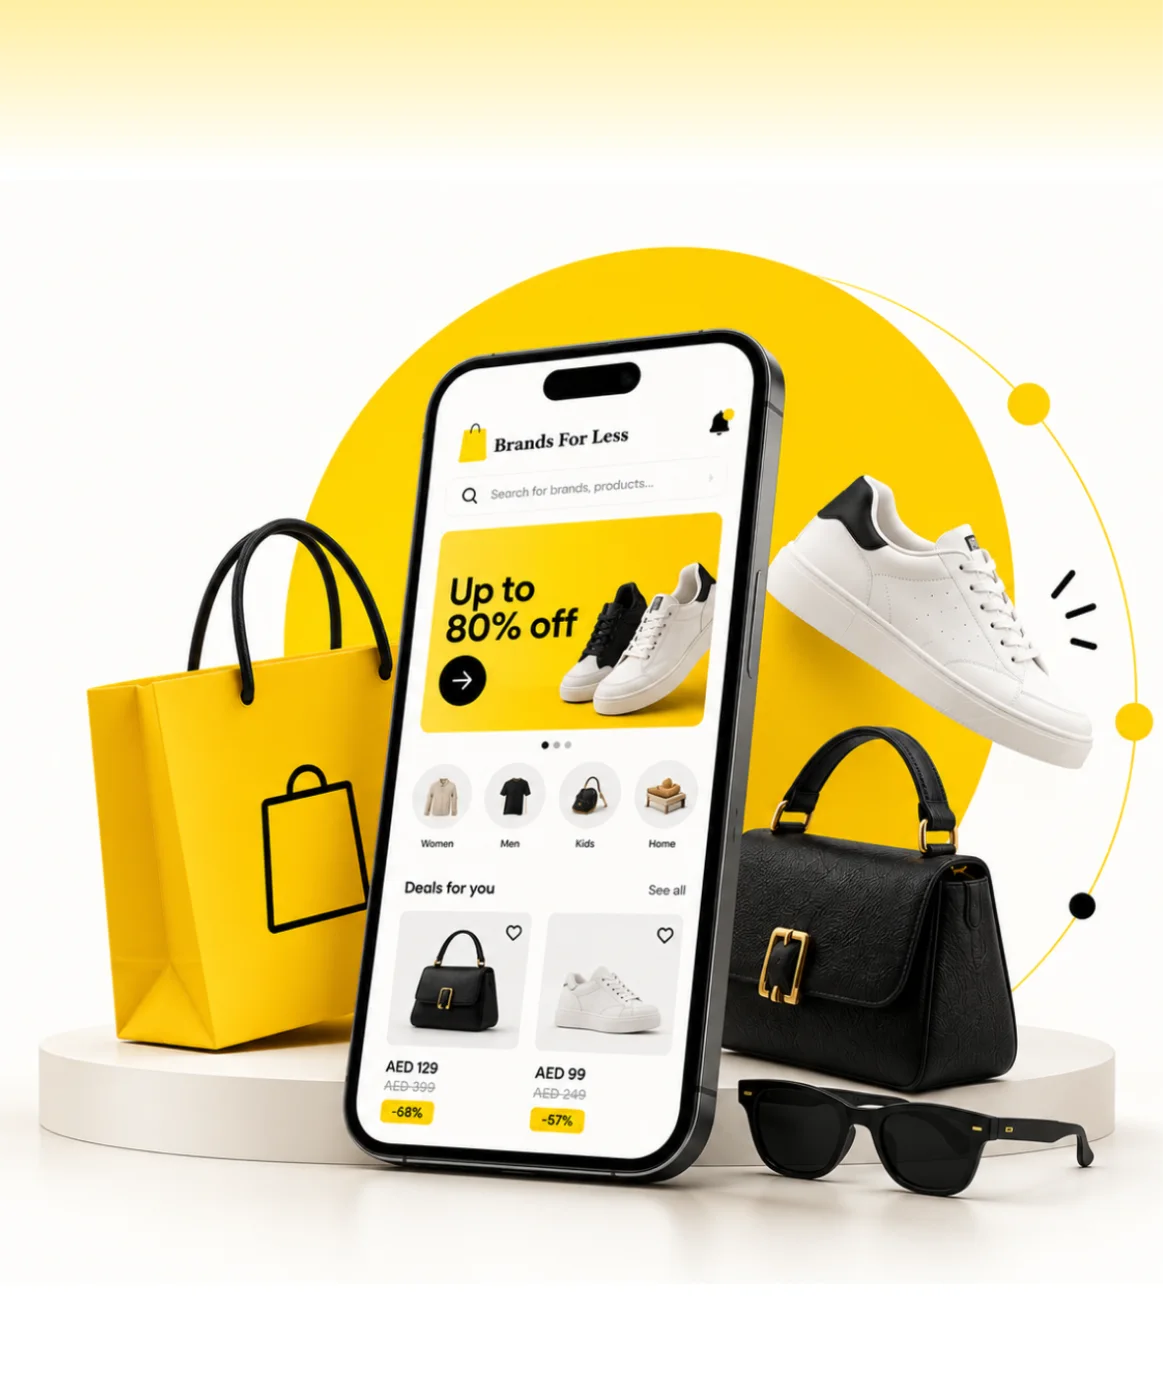
Brands For Less
Found where shoppers dropped off, then redesigned sign-up, banners and cart for a retailer with 120+ stores.
Omantel
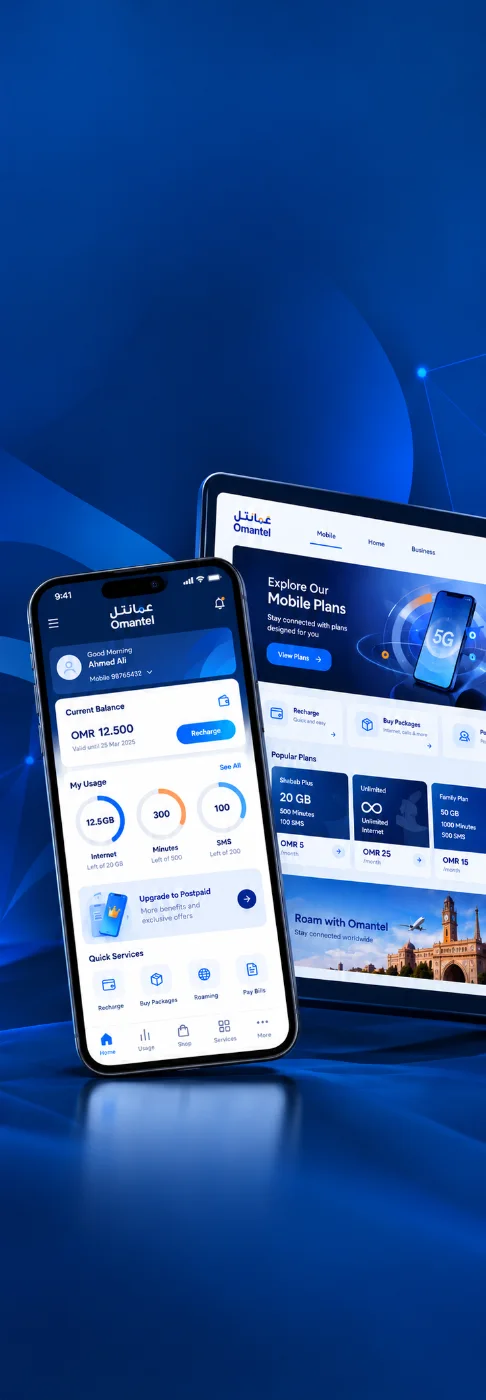
Incident, SLA and workload reporting in one Power BI suite for Oman’s first telecom operator.



Client Testimonials
Client Success: Panda
We reworked Panda's live app and website, from search to checkout, for shoppers across Saudi Arabia.
"Thanks to UIUX Studio’s work, the client successfully launched their websites. The team maintained a professional approach and scheduled frequent in-person meetings to provide suggestions for improving the project and ensuring its timely delivery."
 Shreya LadCEO, Nutroponics
"The team is well-versed in the UI/UX domain and has designed a fantastic journey to support the site’s growth projection. Communication, timeliness, and quality of work have been very professional."
 Mohammed AbdullahZeaara.com
"The Studio has been an absolute game changer for us. After working on a few independent projects, they are now also helping our marketing team, proving their value to our business and earning praise from executives."
 BrandonProject Manager
"The UIUX Studio team consistently delivers exceptional work with dedication. We’ve completed an amazing app design together, and I’m excited to collaborate with them again in the future."
 Hani Farajvancouverhousefinders.com
"We are really pleased with the work that UIUX Studio team has completed for us in designing a website for a new brand. They completed the designs quickly, took on board changes, and the finished product is very professional."
 AnayaHead of Marketing, Freshminds
"I’ve worked with UIUX Studio team on two projects. They capture the vision and run with it! They create exceptional design! Couldn’t be happier with the quality work and files for my developers."
 Brandon PugmirePresident, Imprint City
 Client Results
Reviewed on Upwork, Trustpilot, Clutch, G2 and GoodFirms


Work With Us
Work with a dedicated AI team, a fixed-scope project or hourly support. Every model gives you the same in-house engineers and designers.
Access a dedicated team of AI engineers and designers, on-site or remote, who build and run your agents alongside your team.
Get StartedGet clear, upfront pricing for a defined AI project, such as a readiness review, a first agent or a production pilot.
Get StartedGet AI engineers by the hour, perfect for prompt and evaluation reviews, model or vendor advice, or fixes to an existing workflow.
Get StartedAccuracy on a holdout set is table stakes. What matters is whether the decision downstream of the model got better.
How much better than the rule or the human process, in the unit the business already tracks. The only number that justifies the project.
Measured against outcomes as they arrive, not against the test split. These diverge more often than anyone expects.
How far input distributions have moved from training, with a threshold that triggers retraining before quality visibly drops.
How often the prediction was acted on. A model overridden most of the time is telling you something about trust or timing.
False positives and negatives weighted by what each actually costs you, because they are almost never equal.
Per thousand predictions and at p95, so the model stays viable as volume grows.
INDUSTRY AI
Pick a sector to see the four layers we deploy, from what users see to how the work is checked.
What your users see
What the agents do
The data the AI uses
How the work is checked
What your users see
What the agents do
The data the AI uses
How the work is checked
What your users see
What the agents do
The data the AI uses
How the work is checked
What your users see
What the agents do
The data the AI uses
How the work is checked
What your users see
What the agents do
The data the AI uses
How the work is checked
What your users see
What the agents do
The data the AI uses
How the work is checked
What your users see
What the agents do
The data the AI uses
How the work is checked
What your users see
What the agents do
The data the AI uses
How the work is checked
Prove value on a single workflow, then reuse the foundation for the next.
Trained models rarely arrive alone. They need a pipeline underneath and usually a workflow above that acts on what they predict.
The serving, monitoring and retraining infrastructure this runs on, shared across every model you deploy.
View service ↗When the goal is understanding what happened rather than predicting what happens next.
View service ↗The workflow that acts on a prediction — routing, escalation and the approval gates around it.
View service ↗Four weeks to decide which prediction problem is worth solving first, and whether your data supports it.
View service ↗Forty-five minutes with a data scientist. We will tell you whether your history can support a model, what a realistic lift looks like, and whether a rule would get you most of the way. No deck, no discovery fee.
Test a model on your dataBook a free consultation with our design, engineering and AI experts. Share your idea and we’ll come back within one business day with clear next steps.
Recognised By


Our Offices

UAE · Headquarters
Office OFF2-127, SMARK 2 Building, Plot No. 33-0, Ras Al Khor Industrial Second, Dubai, UAE

India
B-409, Bestech Business Tower, Sector 66, SAS Nagar, Punjab 160062

Australia
Tapleys Hill Road, Fulham Gardens, SA 5024