




Offshore / Onsite
Hire Dedicated Team
Access a dedicated team of AI engineers and designers, on-site or remote, who build and run your agents alongside your team.
Get StartedAn AI chatbot or assistant is only useful if people trust what it says. We build retrieval over your own content, cite every claim back to the document it came from, and refuse to answer when the evidence is not there.
Our Clients










They abandon it because it was confidently wrong once, in front of a customer or a colleague. Everything we build is arranged around making that specific failure rare and visible.
It answers from the model’s general knowledge rather than your policy, so the reply sounds plausible and contradicts the handbook.
Retrieval first, generation second. If nothing relevant is retrieved, the assistant says it does not know rather than filling the gap.
No citation, so a reader cannot check it and stops trusting it after the first surprise.
Every claim links to the paragraph it came from. Users check the source once, find it accurate, and stop needing to.
Everyone sees everything, because permissions were bolted on after the index was built.
Access is enforced at retrieval time against your existing groups, so two users asking the same question get different, correct answers.
Content goes stale. The index was built once and the documents moved on without it.
Incremental re-indexing on a schedule, with a freshness report so you can see what the assistant is actually reading.
The interface is the easy part. Almost all of the work — and all of the trust — lives in the layers underneath it.
Your documents, tickets, wiki and product data parsed, chunked and kept current, with a report on what is indexed and what failed to parse.
Hybrid keyword and semantic search tuned on your own questions, because generic retrieval settings are the most common cause of wrong answers.
Access checked at query time against your existing groups and roles, so the assistant does not surface a document a user could not open.
Answers assembled only from retrieved passages, with citations, and an explicit refusal path when the evidence is thin.
A question set drawn from real user queries, scored on every change, so a prompt tweak cannot quietly degrade accuracy.
The web widget, in-app panel or Slack and Teams integration — with streaming, feedback capture and a visible confidence signal.
The common thread is a question asked hundreds of times a week, with the answer already written down somewhere nobody can find.
Tier-one questions answered from your help centre and policy documents, with a clean handover to a human the moment the answer is not there.
Your support team gets the cited answer in the console while the customer is still on the line, rather than searching three systems.
Policy, process and IT questions answered from the handbook, respecting who is allowed to see which document.
Reps get product, pricing and competitor answers sourced from approved material rather than from memory.
New starters and new customers ask the questions they would otherwise queue for, at whatever hour they are working.
Contracts, specifications and reports queried directly, with the passage shown so a professional can verify before acting.
Accuracy is measured on your real questions before we build the interface. If retrieval cannot answer them, no amount of prompt work will fix it, and we would rather know in week two.
We take fifty real questions from your team and check whether the answers exist in your documents at all. Roughly a fifth of the time they do not, and that is the finding that matters most.
A retrieval-only prototype scored on those questions, with no interface and no polish. This number decides whether the project proceeds, and it is far more predictive than any demo.
Grounded generation with citations, the refusal path for thin evidence, and permission enforcement checked at query time against your existing groups.
The question set becomes a test suite that runs on every change, plus adversarial testing on prompt injection and permission boundaries.
A staged rollout by audience, with feedback capture on every answer. The first month of real questions is the most useful tuning data you will ever get.
Running in your cloud account, on components you can swap. The retrieval layer matters more than the model, and both stay yours to change.


Running in your cloud account, on components you can swap. The retrieval layer matters more than the model, and both stay yours to change.


Running in your cloud account, on components you can swap. The retrieval layer matters more than the model, and both stay yours to change.

Running in your cloud account, on components you can swap. The retrieval layer matters more than the model, and both stay yours to change.

Running in your cloud account, on components you can swap. The retrieval layer matters more than the model, and both stay yours to change.




Case Studies
Selected work for retail, banking, telecom and defence teams, from brand identity and mobile apps to data platforms and AI assistants.
Panda
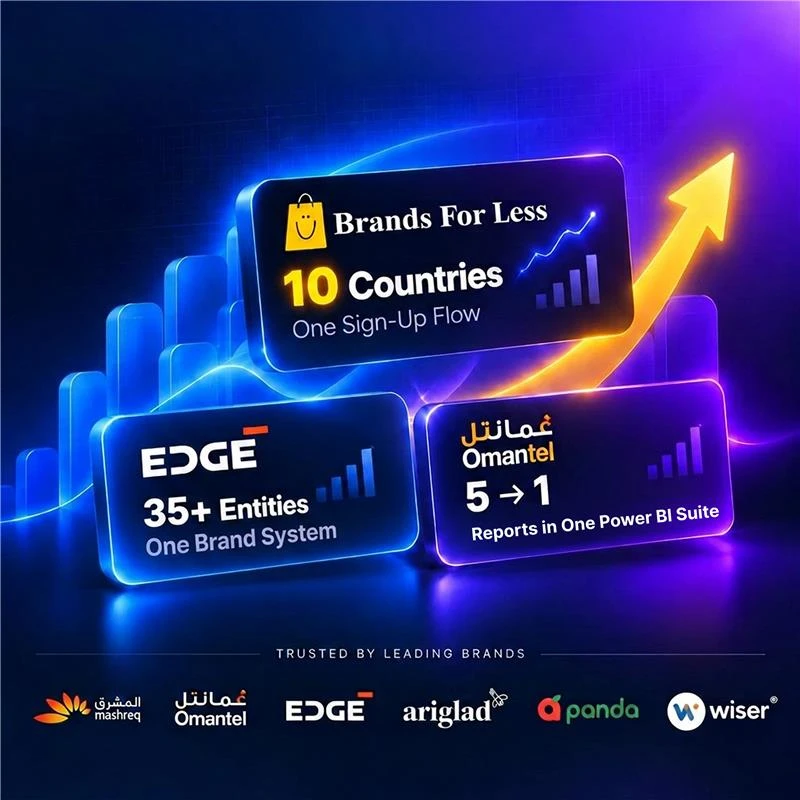
Reworked search, categories and checkout in Panda’s live app and website, in Arabic and English.
EDGE Group
Brand identity, website and print for a group of 12,000 staff, carried onto the IDEX show floor.
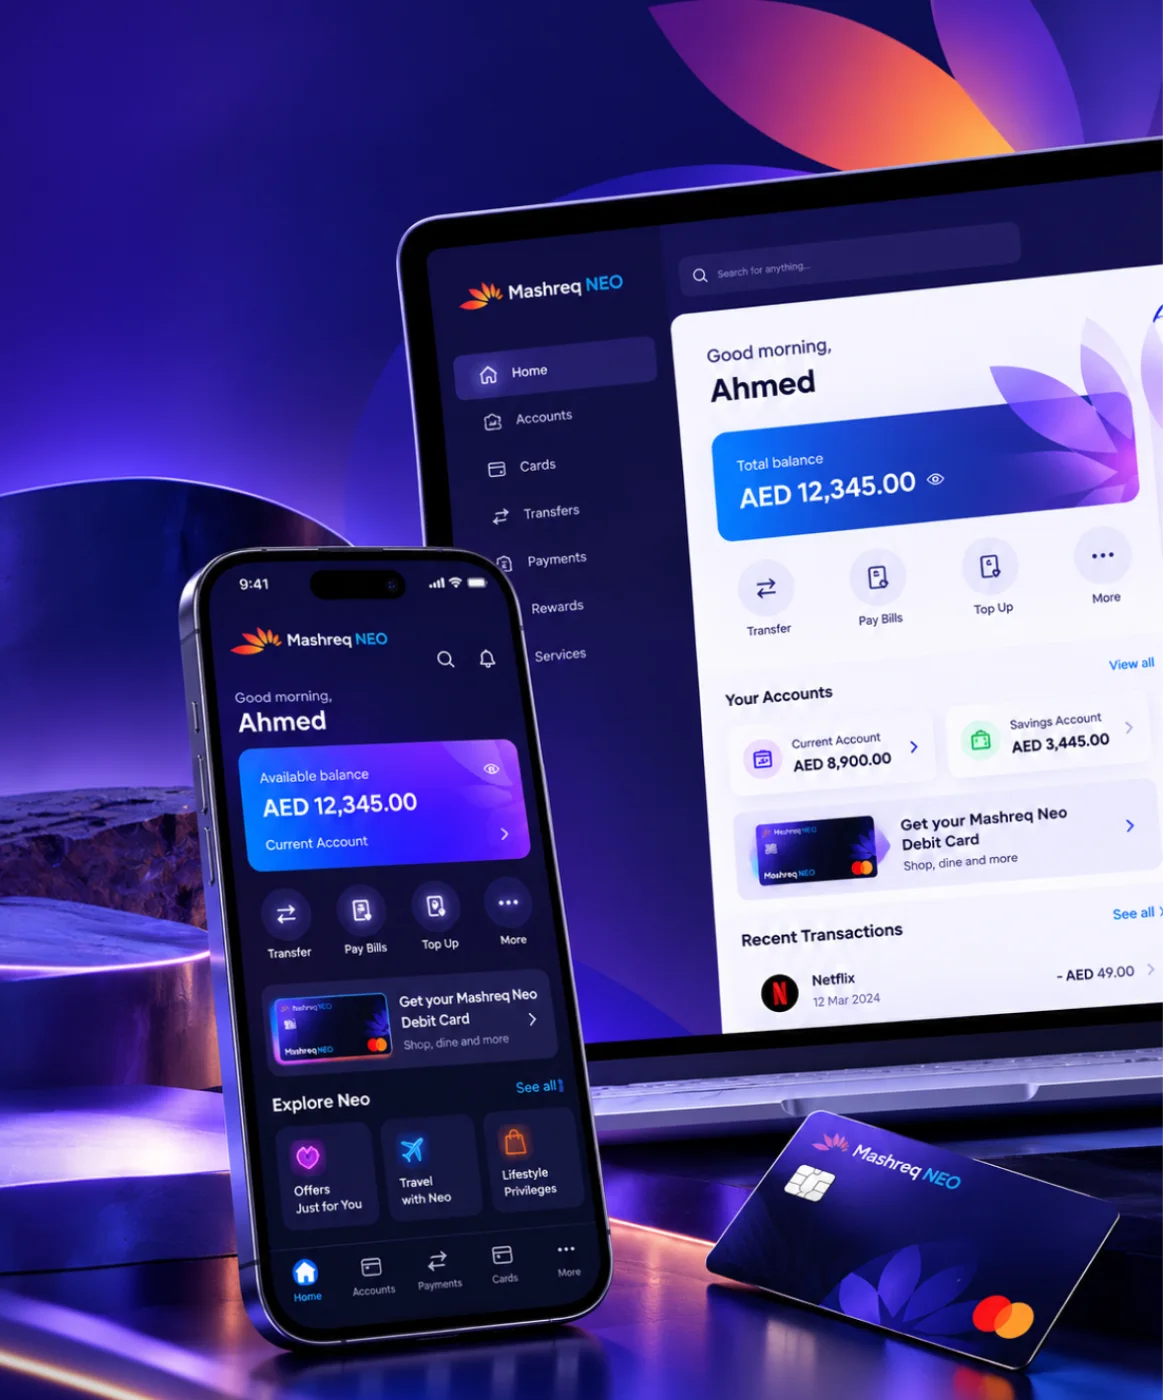
Mashreq NEO
Six performance areas in one index for leadership, plus NEO GPT, a private assistant for bank documents.
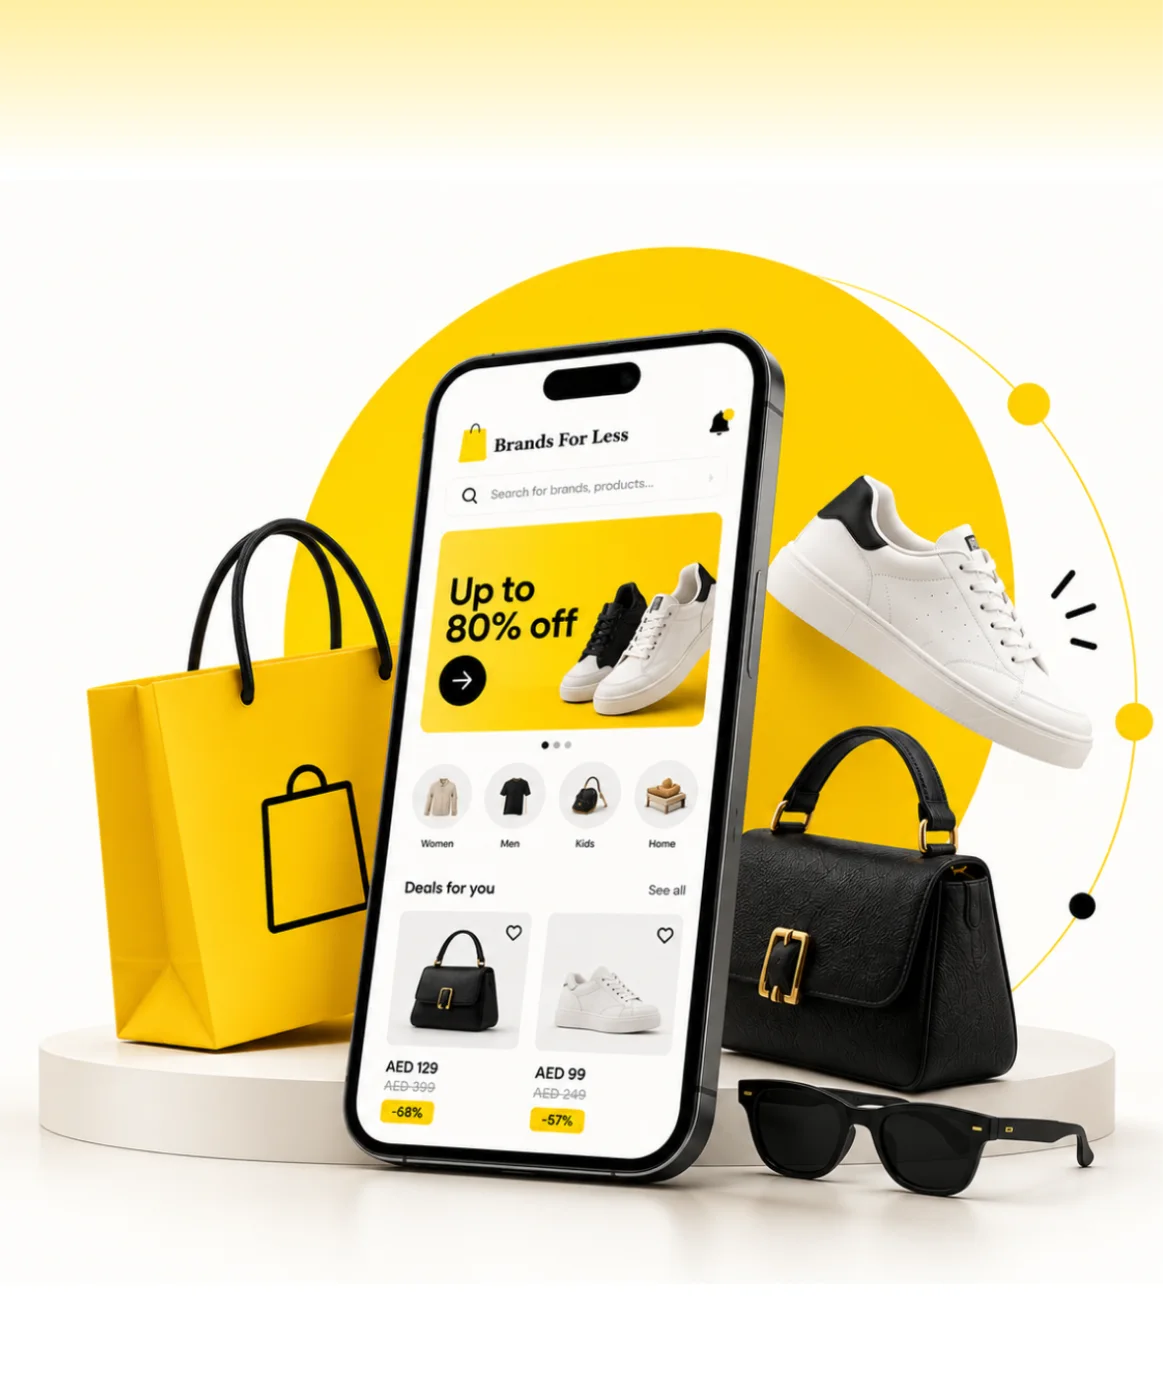
Brands For Less
Found where shoppers dropped off, then redesigned sign-up, banners and cart for a retailer with 120+ stores.
Omantel
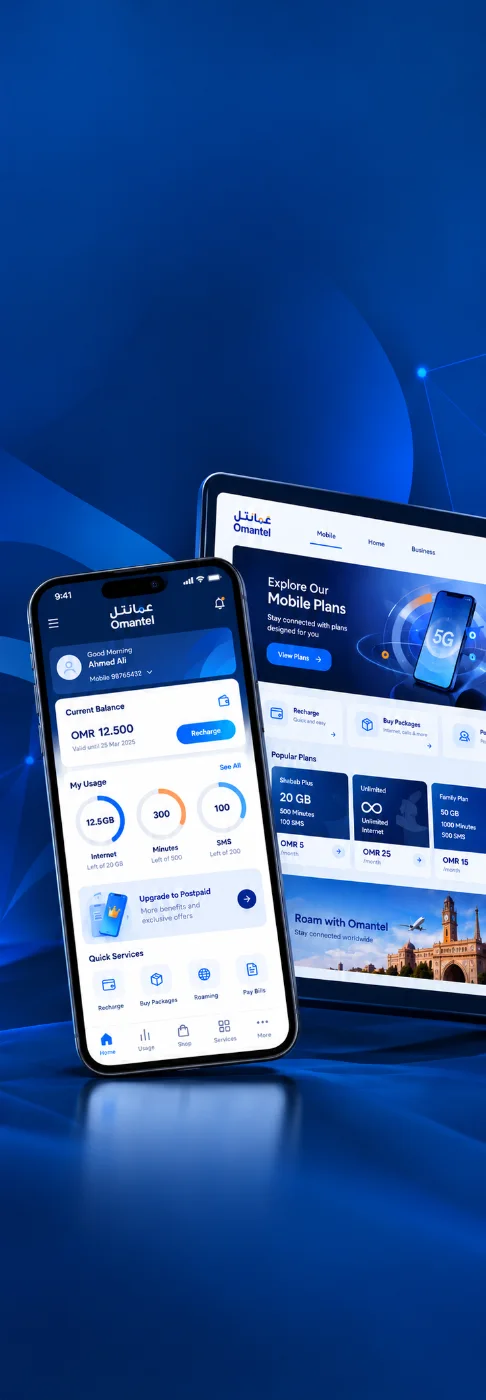
Incident, SLA and workload reporting in one Power BI suite for Oman’s first telecom operator.



Client Testimonials
Client Success: Panda
We reworked Panda's live app and website, from search to checkout, for shoppers across Saudi Arabia.
"Thanks to UIUX Studio’s work, the client successfully launched their websites. The team maintained a professional approach and scheduled frequent in-person meetings to provide suggestions for improving the project and ensuring its timely delivery."
 Shreya LadCEO, Nutroponics
"The team is well-versed in the UI/UX domain and has designed a fantastic journey to support the site’s growth projection. Communication, timeliness, and quality of work have been very professional."
 Mohammed AbdullahZeaara.com
"The Studio has been an absolute game changer for us. After working on a few independent projects, they are now also helping our marketing team, proving their value to our business and earning praise from executives."
 BrandonProject Manager
"The UIUX Studio team consistently delivers exceptional work with dedication. We’ve completed an amazing app design together, and I’m excited to collaborate with them again in the future."
 Hani Farajvancouverhousefinders.com
"We are really pleased with the work that UIUX Studio team has completed for us in designing a website for a new brand. They completed the designs quickly, took on board changes, and the finished product is very professional."
 AnayaHead of Marketing, Freshminds
"I’ve worked with UIUX Studio team on two projects. They capture the vision and run with it! They create exceptional design! Couldn’t be happier with the quality work and files for my developers."
 Brandon PugmirePresident, Imprint City
 Client Results
Reviewed on Upwork, Trustpilot, Clutch, G2 and GoodFirms


Work With Us
Work with a dedicated AI team, a fixed-scope project or hourly support. Every model gives you the same in-house engineers and designers.
Access a dedicated team of AI engineers and designers, on-site or remote, who build and run your agents alongside your team.
Get StartedGet clear, upfront pricing for a defined AI project, such as a readiness review, a first agent or a production pilot.
Get StartedGet AI engineers by the hour, perfect for prompt and evaluation reviews, model or vendor advice, or fixes to an existing workflow.
Get StartedConversation counts and session length tell you nothing about whether the thing is working. These do.
Sampled answers scored against your own subject-matter judgement, reported per topic rather than as one average.
Whether the cited passage genuinely supports the claim. A correct answer with a wrong source still counts as a failure.
How often it declined, and whether it should have. Both over-confidence and over-caution are tracked.
Tickets not raised, or minutes saved per query, depending on which one your team already reports.
The questions users asked that your content cannot answer — handed to your team as a documentation backlog.
Fully loaded, including re-indexing and the human review that escalated cases still need.
INDUSTRY AI
Pick a sector to see the four layers we deploy, from what users see to how the work is checked.
What your users see
What the agents do
The data the AI uses
How the work is checked
What your users see
What the agents do
The data the AI uses
How the work is checked
What your users see
What the agents do
The data the AI uses
How the work is checked
What your users see
What the agents do
The data the AI uses
How the work is checked
What your users see
What the agents do
The data the AI uses
How the work is checked
What your users see
What the agents do
The data the AI uses
How the work is checked
What your users see
What the agents do
The data the AI uses
How the work is checked
What your users see
What the agents do
The data the AI uses
How the work is checked
Prove value on a single workflow, then reuse the foundation for the next.
An assistant is usually the first thing a team ships and rarely the last. These are the services most often scoped before or after it.
Four weeks to decide whether this is the right first build, and what running it costs at real volume.
View service ↗When users need the work done rather than explained — agents that take real actions with approval gates.
View service ↗The retrieval infrastructure, model gateway and evaluation harness this runs on.
View service ↗Document intelligence where the goal is extraction and routing rather than conversation.
View service ↗Forty-five minutes with an engineer. We will tell you how many of them your existing content can actually answer, where the gaps are, and whether an assistant is the right fix. No deck, no discovery fee.
Test it on your contentBook a free consultation with our design, engineering and AI experts. Share your idea and we’ll come back within one business day with clear next steps.
Recognised By


Our Offices

UAE · Headquarters
Office OFF2-127, SMARK 2 Building, Plot No. 33-0, Ras Al Khor Industrial Second, Dubai, UAE

India
B-409, Bestech Business Tower, Sector 66, SAS Nagar, Punjab 160062

Australia
Tapleys Hill Road, Fulham Gardens, SA 5024